Image Downloader
The Image Downloader scans the current page for every image — including lazy-loaded, hidden, and CSS background images — and lets you download them individually or as a single ZIP file. In the side panel it's called Download images.
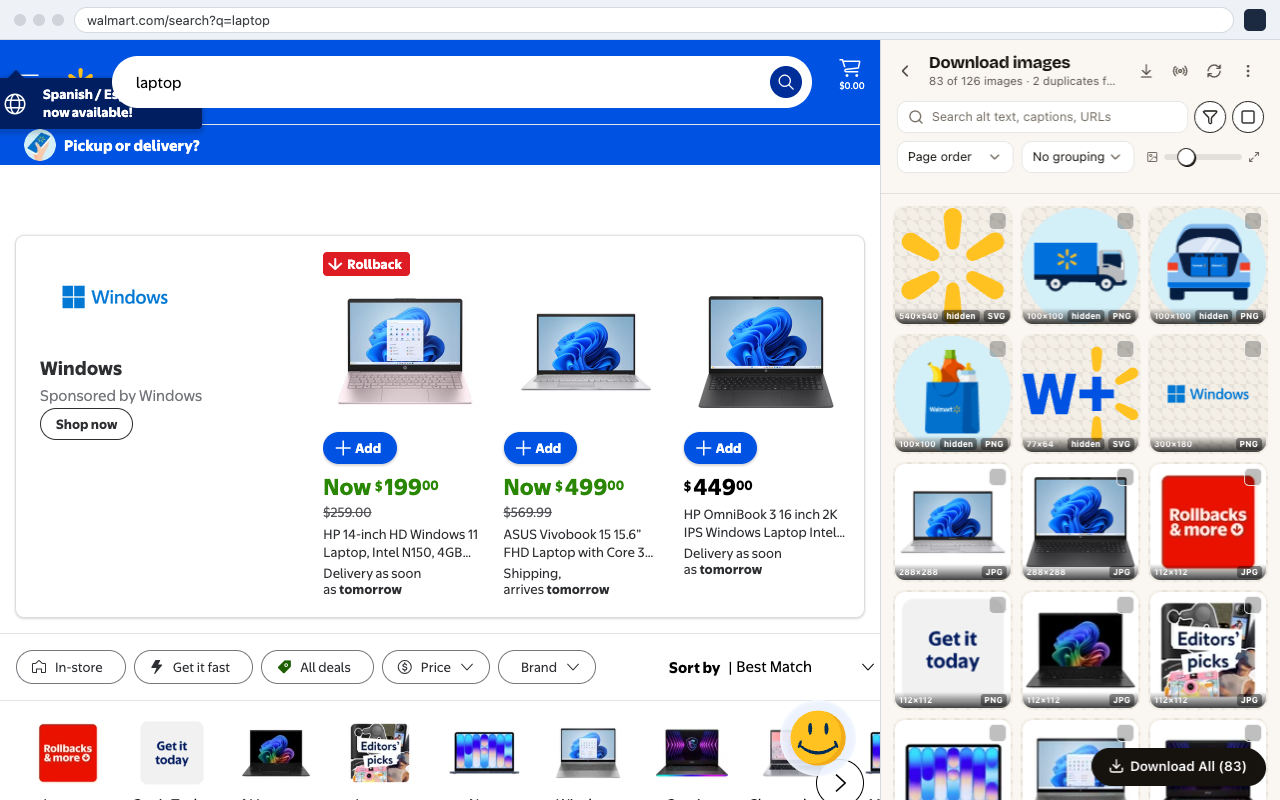
When to Use It
- Downloading product images from an e-commerce page
- Archiving images from a photo gallery or portfolio site
- Collecting reference images for design research
- Downloading avatars, icons, or thumbnails from a listing page
Step 1 — Navigate to the Target Page
Go to the page containing the images you want. If it's an infinite-scroll gallery, scroll through the page first to trigger lazy loading before scanning.
Step 2 — Scan for Images
Open CrawlPilot → Images. CrawlPilot scans the page as soon as the screen opens, and the refresh icon scans it again.
CrawlPilot detects images from all these sources:
| Source | What's detected |
|---|---|
<img> tags | src attribute; also data-src, data-original for lazy-loaded images |
<picture> / <source> | Responsive image sources at all breakpoints |
| CSS background images | background-image styles on any element |
| Video poster frames | <video poster="..."> attributes |
| Canvas elements | Converted to PNG data URLs |
| SVG elements | Extracted or converted to PNG |
Detected images appear in a grid with their dimensions and estimated file size.
Step 3 — Filter Images
Use the size filter tabs to focus on what you need:
| Filter | Size range |
|---|---|
| Small | Under 100 × 100 px (icons, thumbnails, avatars) |
| Medium | 100 – 500 px (banners, thumbnails, product images) |
| Large | Over 500 px (full-quality photos, hero images) |
Step 4 — Select Images
- Click any image to select it (highlighted border appears)
- Click again to deselect
- Click Select All to grab all visible images at once
Step 5 — Download
- Download Selected — packages all selected images into a
.zipfile and triggers a download - Click any single image thumbnail — downloads just that image
Downloaded files keep their original filename. ZIP files are named crawlpilot-images-[timestamp].zip.
Supported Formats
JPG · PNG · GIF · SVG · WebP · AVIF
CORS and Protected Images
Some images are hosted on different domains and block direct access (CORS). CrawlPilot routes these downloads through an extension-level background proxy that bypasses CORS restrictions — you see them in the grid and can download them just like any other image.
Example: Downloading Product Images
Goal: Download all high-res product photos from a product detail page.
- 01Open the product page in Chrome. Scroll down to ensure all images are loaded.
- 02Open Image Downloader → Scan Page.
- 03Switch to the Large filter.
- 04Click Select All.
- 05Click Download Selected.
- 06A ZIP file downloads with all product images using their original filenames.
Troubleshooting
Images appear broken in the grid: The image URL is valid but the file couldn't be fetched — this can happen with heavily CORS-restricted CDNs. Try right-clicking the image on the page and saving it manually.
0×0 dimension images appear: These are tracking pixels or invisible elements. They are filtered out automatically.
Video posters missing: Some video players load the poster dynamically. Scroll the video into view and re-scan.