List Extractor
In the side panel this tool is called Get a list from this page. The List Extractor pulls structured data from pages that display repeated items — product grids, article feeds, job listings, directory tables, and anything with a consistent repeating pattern.
It supports single-page extraction as well as multi-page collection via infinite scroll, "Load More" buttons, and classic next-page pagination.
When to Use It
- A page shows 50 products and you want all their names, prices, and URLs
- A blog lists 200 articles with titles and dates across 10 pages
- A job board shows listings with infinite scroll
- A directory table has rows you want as spreadsheet data
The 3 Steps: Pick, Pages, Get Data
Open CrawlPilot on a page with a list and click Get them as a table on the home screen, or A list under Or choose what you want. The panel walks you through three steps, shown at the top as Pick → Pages → Get data.
Step 1 — Pick: Point at One Item
Click Point at one item, then hover over one product, result or row on the page. CrawlPilot highlights the whole list it belongs to and labels it with the item count.
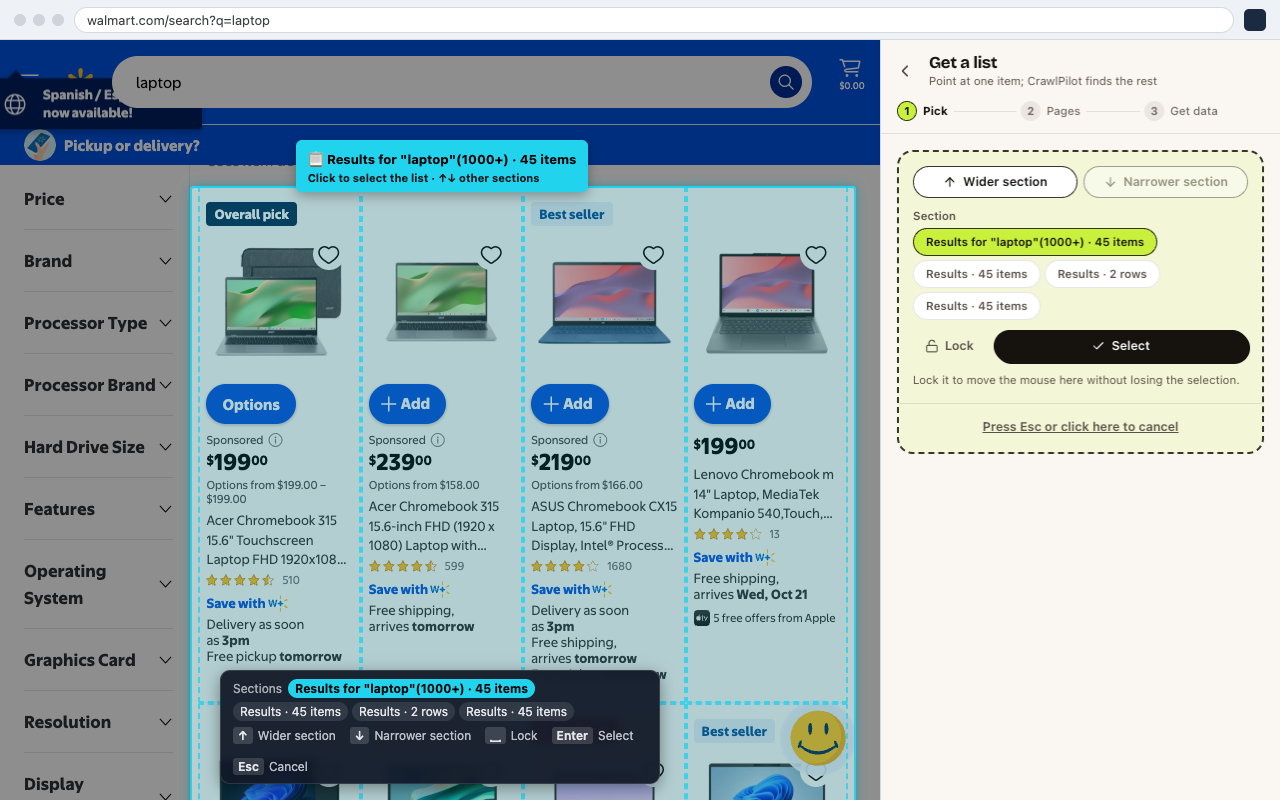
- Press ↑ (Wider section) or ↓ (Narrower section) if the highlight covers too much or too little. The panel lists the sections it found, with their item counts.
- Lock keeps the selection while you move the mouse to the panel.
- Click the item, or press Enter (Select), to pick the list. Esc cancels.
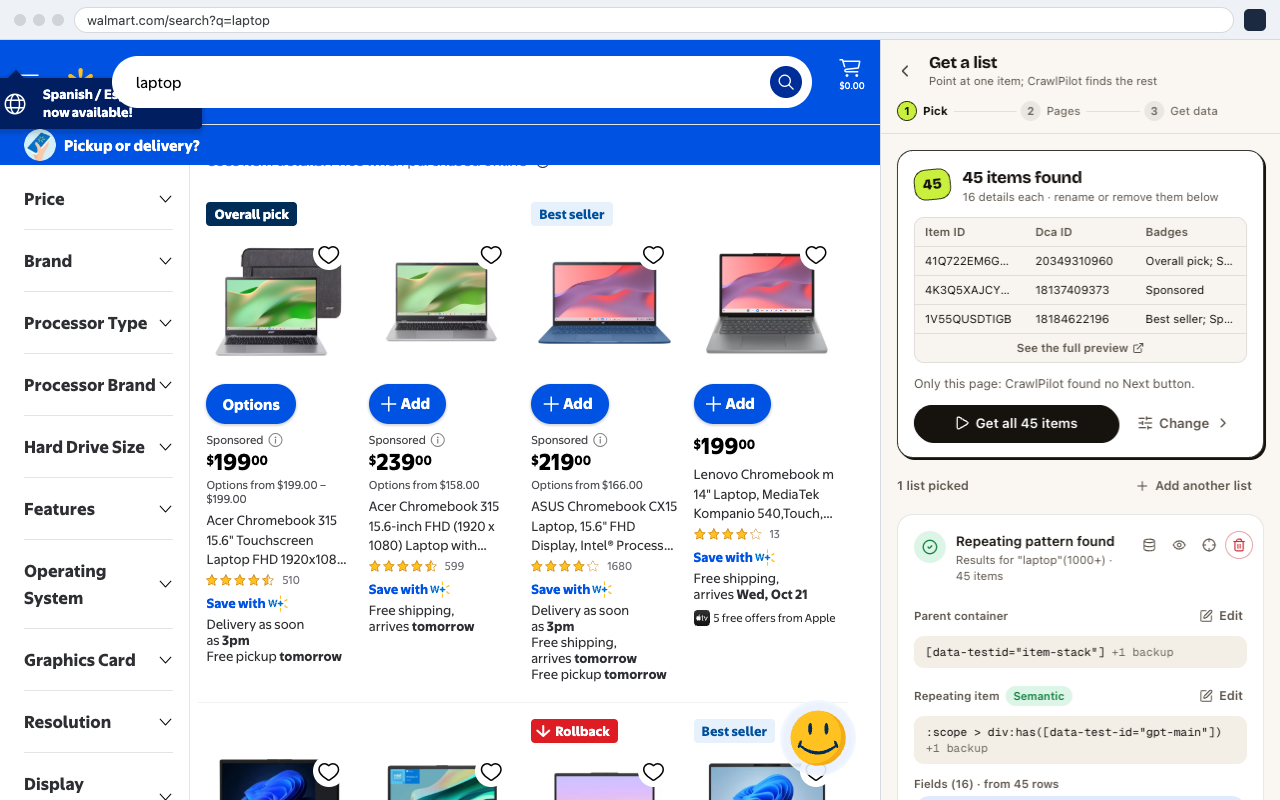
CrawlPilot then reads every item and finds its details: titles, prices, ratings, review counts, links and images. Fields are typed, and values a site packs together are split into separate columns.
From here:
- See the full preview opens every row and column.
- Under the picked list you can Edit the selectors, rename or remove details, and Add another list from the same page.
- If you're happy, click Get all N items or Get the data from N pages to run straight away. Click Change to adjust pages and settings first.
Step 2 — Pages: Does the List Go On?
CrawlPilot looks for a Next link by itself. The line above the button tells you what it will do, for example Then follows "Next Page" through up to 3 pages, or Only this page: CrawlPilot found no Next button. To choose yourself, click Change:
| Option | Use when |
|---|---|
| Pages with a Next button | Page numbers, or a Next › link at the bottom |
| A "Load more" button | More items appear on the same page when you click it |
| Scrolling, or all on one page | More items appear as you scroll, or there's only this page |
For button-based options, click Point at the button and then click the Next or Load more button on the page once.
Step 3 — Get Data
Check the summary, set Pages to read at most, and click Get the data.
- Keep the side panel open while the run goes on: closing it stops the run. You can switch to other screens and tabs.
- Stop ends the run at any time and keeps every row read so far.
When it finishes, the panel shows Done with the number of items and pages:
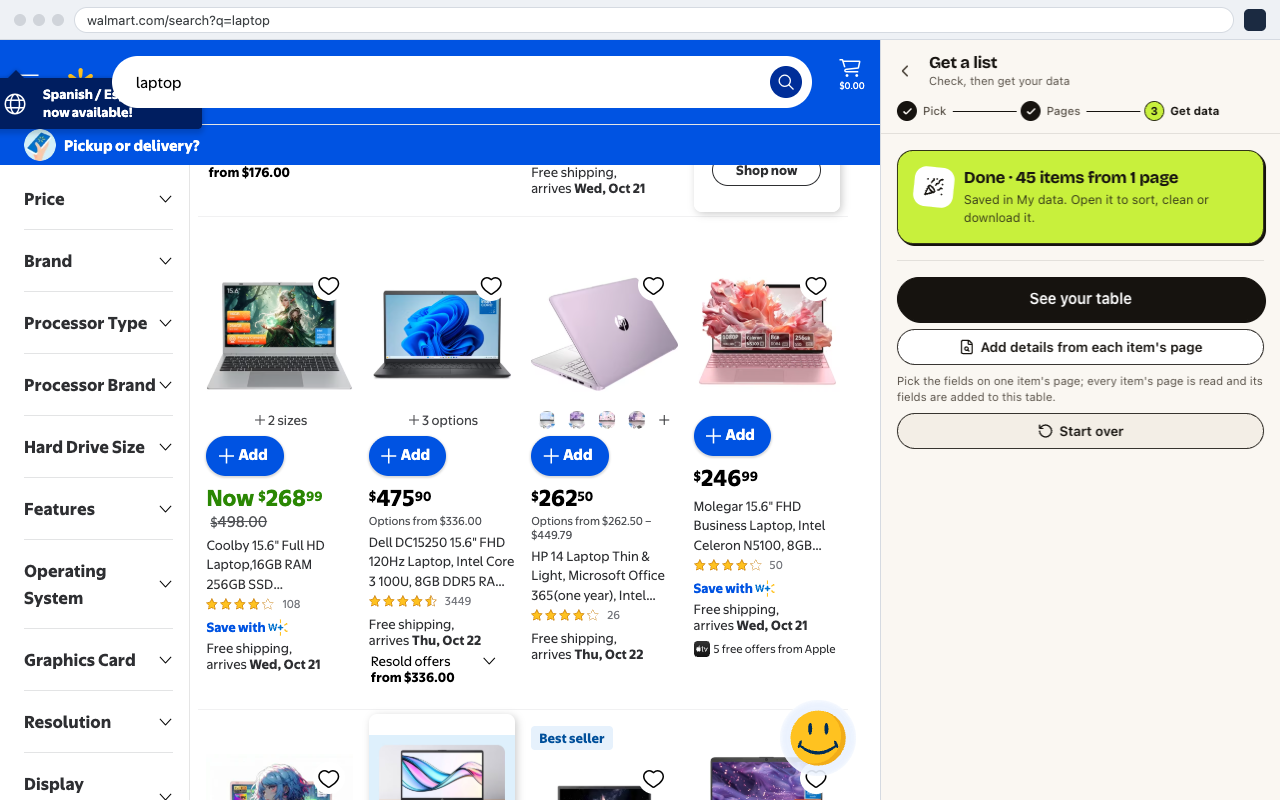
- See your table opens the data in a full tab, where you can sort, clean and export it.
- Add details from each item's page: pick fields on one item's page, and CrawlPilot reads every item's page and adds those fields as new columns.
- Start over picks a new list.
Example: Laptops from a Walmart Search
Goal: title, price, rating and link for every laptop in a Walmart search.
- 01Search Walmart for "laptop" and open CrawlPilot.
- 02The home screen says 45 products on this page. Click Get them as a table.
- 03Click Point at one item and click one laptop card.
- 04Check the preview: 45 items found, 16 details each.
- 05Click Get the data from N pages to follow the Next link, or Change to read only this page.
- 06Click See your table → Export → Excel (.xlsx).
Handling Duplicate Rows
CrawlPilot automatically deduplicates rows at two levels:
- 01In-memory: During the scroll session, duplicate rows are dropped before they reach storage
- 02Database: A hash-based unique constraint ensures no true duplicates are ever stored
Example: Scraping an E-commerce Product Grid
Goal: Collect title, author, price, and product URL for 200 books from an online bookstore.
- 01Open the bookstore's category page.
- 02Open CrawlPilot → List Extractor.
- 03Pick Container: hover over
<div class="book-grid">(all books highlight together). - 04Pick Item: hover over one
<div class="book-card">. - 05Schema auto-detects: Title (h3), Author (span.author), Price (span.price), URL (a href).
- 06Set pagination to Pagination — Next Button, click the "Next ›" button.
- 07Set Max Pages to 20, Speed to Medium.
- 08Click Start — watch the count climb to 200.
- 09Click View Data → Export CSV.
Selector Editor
For advanced users, every auto-detected selector can be manually edited:
- 01Under the picked list, click Edit next to Parent container, Repeating item, or a field.
- 02Enter a CSS selector or XPath expression.
- 03Check the result in the preview before you run.
Each selector keeps a backup (shown as +1 backup), which CrawlPilot falls back to when a site changes its layout.
XPath example for a specific attribute:
//div[@class='price']/@data-price