Page Extractor
In the side panel this tool is called Same details from many pages. You give it a list of pages and choose the details once. CrawlPilot reads every page and returns one row per page: prices and SKUs from 500 product pages, titles and authors from 100 articles, or anything else that sits in the same place on each page.
When to Use It
- You have product, job or profile URLs and need the same fields from each
- You want the full text of a reading list, for notes or an LLM
- A page needs a click first (a cookie banner, a "Show more" or a tab) before the data appears
To get the URLs in the first place, use Get a list from this page on a category or search page. Then either use its link column here, or click Add details from each item's page when the list finishes.
The tool has three steps, shown at the top of the panel: Details → Pages → Run.
Step 1 — Details: What Do You Want?
Open CrawlPilot on one of the pages → Many pages. The first question is Which details do you want?:
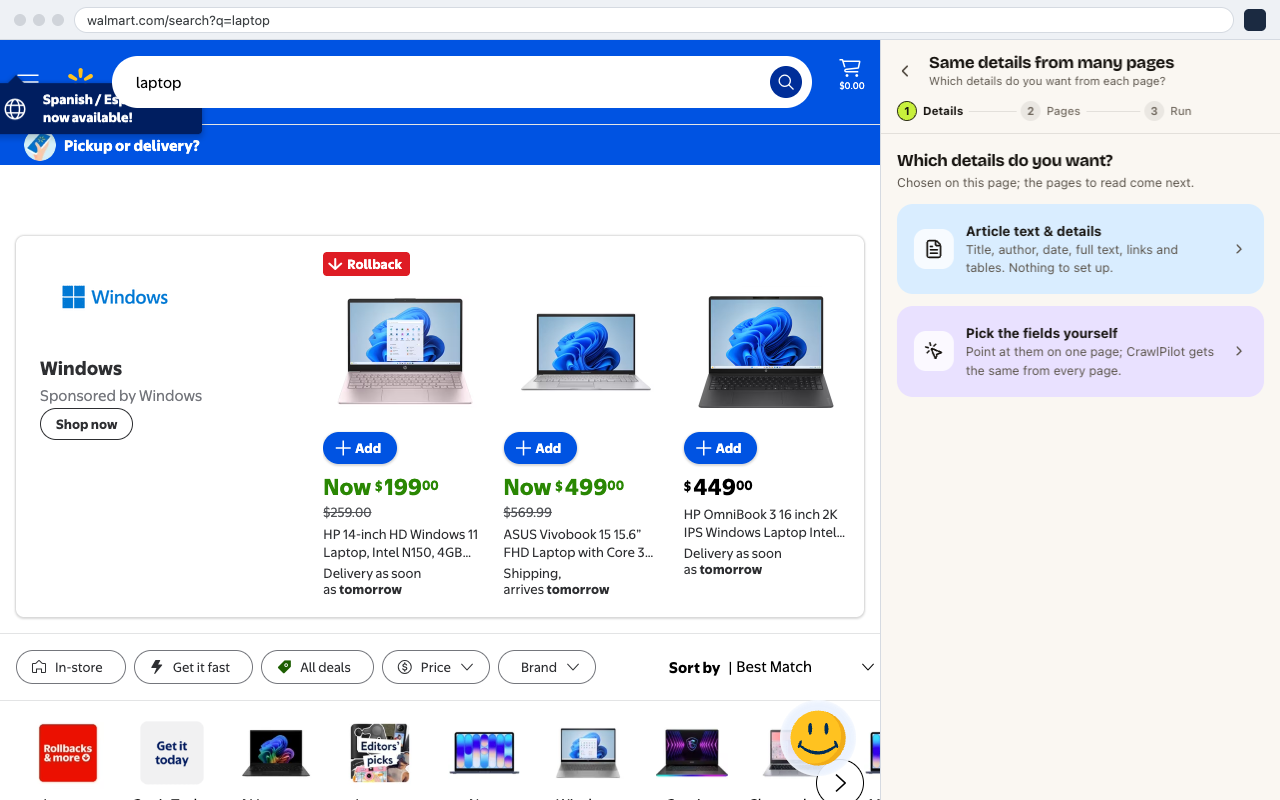
Article text & details gets the title, author, date, full text, links and tables, with nothing to set up. See Metadata Extractor for what it collects.
Pick the fields yourself: point at each field on this page, and CrawlPilot gets the same from every page.
- 01Under Pick the fields, point at what you want on the page, such as the price, and click it.
- 02Name the field and choose What to take: Text (the default), Link (href), Image (src), List of texts, or Table (rows).
- 03If the highlight is too small or too big, use Adjust on the page (wider or narrower).
- 04Click Save field, then Add field for the next one.
- 05Pick data fields offers what the page already publishes about itself (price, images, specs). Fields read this way are marked Page data and keep working when the site changes its layout.
- 06If something has to be opened first, click Add a click: open tabs, dropdowns or "Show more", or close a cookie banner.
- 07Click Next: pages.
Each field stores its selectors best first, with backups (CSS or XPath, one per line), so a field still works when one selector stops matching.
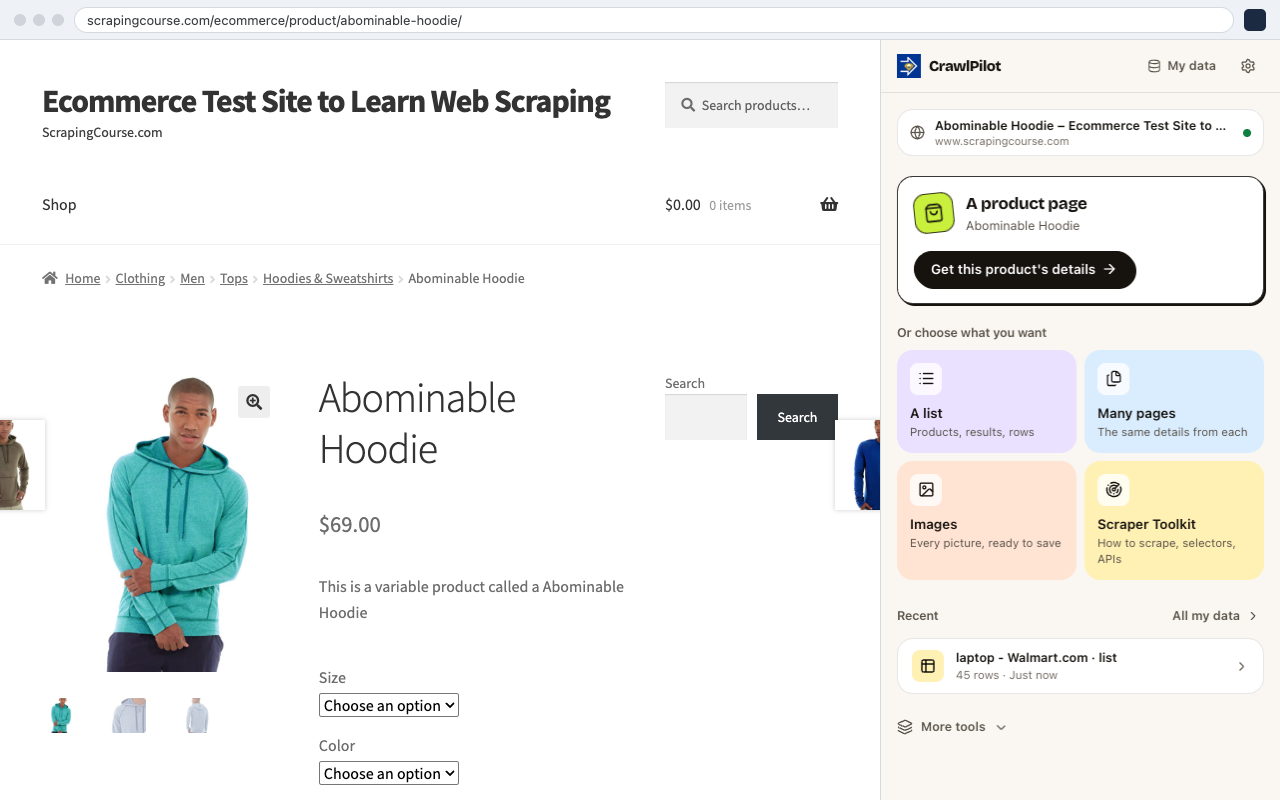
On a single product page, the home screen offers this tool directly with Get this product's details:
Step 2 — Pages: Which Pages to Read?
The page you're on is added for you. Click Choose a different source to add more pages:
| Source | What it adds |
|---|---|
| This page | The page open in this tab |
| Upload a file | A CSV with one page address per row, or one URL per line |
| A list you saved | The links in a table you already have in My data |
| Find pages on this site | Pages from the site's sitemap, grouped by kind of page. Filter with Only URLs like or Skip URLs like |
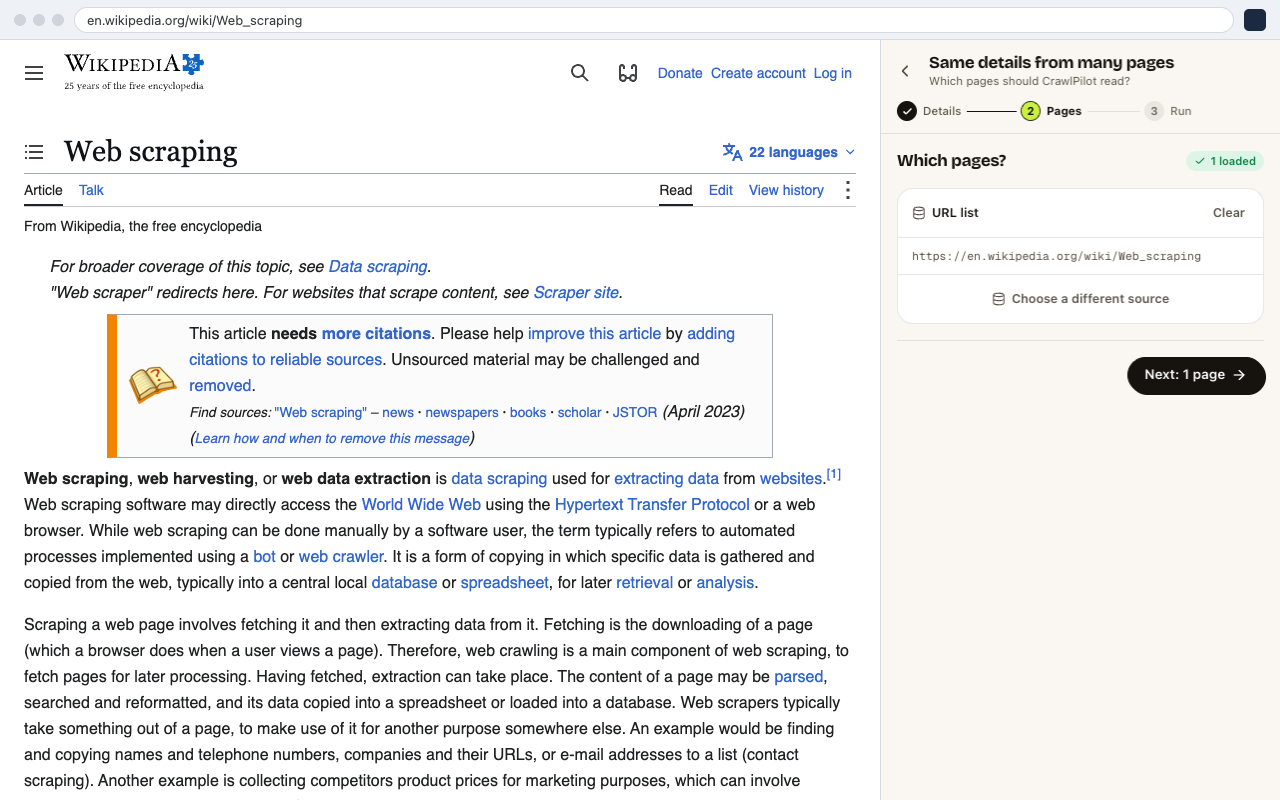
Click Next: N pages.
Step 3 — Run
Check the summary and options, then click Get N pages:
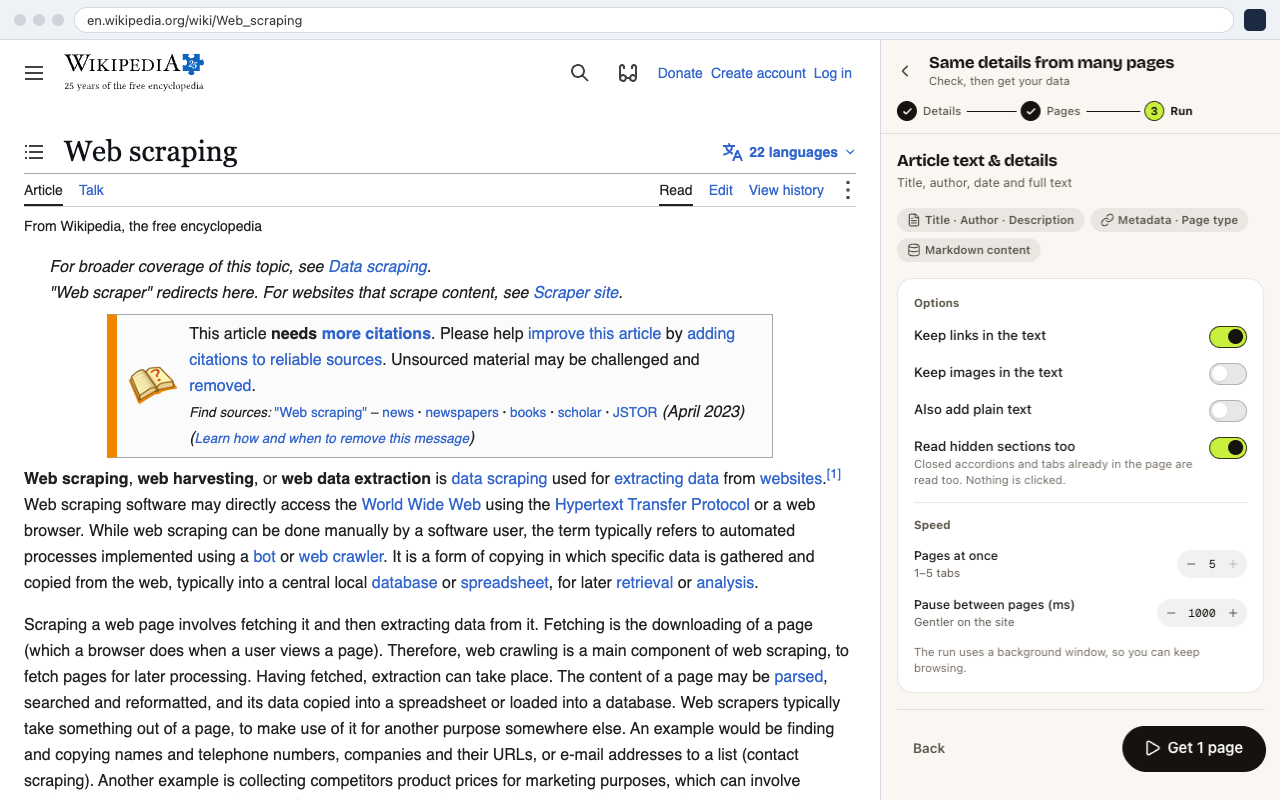
- Pages at once (1–5 tabs) and Pause between pages set the speed. A pause is gentler on the site. CrawlPilot suggests a number of tabs that suits your computer, and eases off when it struggles.
- The run uses a background window, so you can keep browsing.
- Stop ends the run and keeps every page read so far. See what's done so far opens the partial table.
When it finishes:
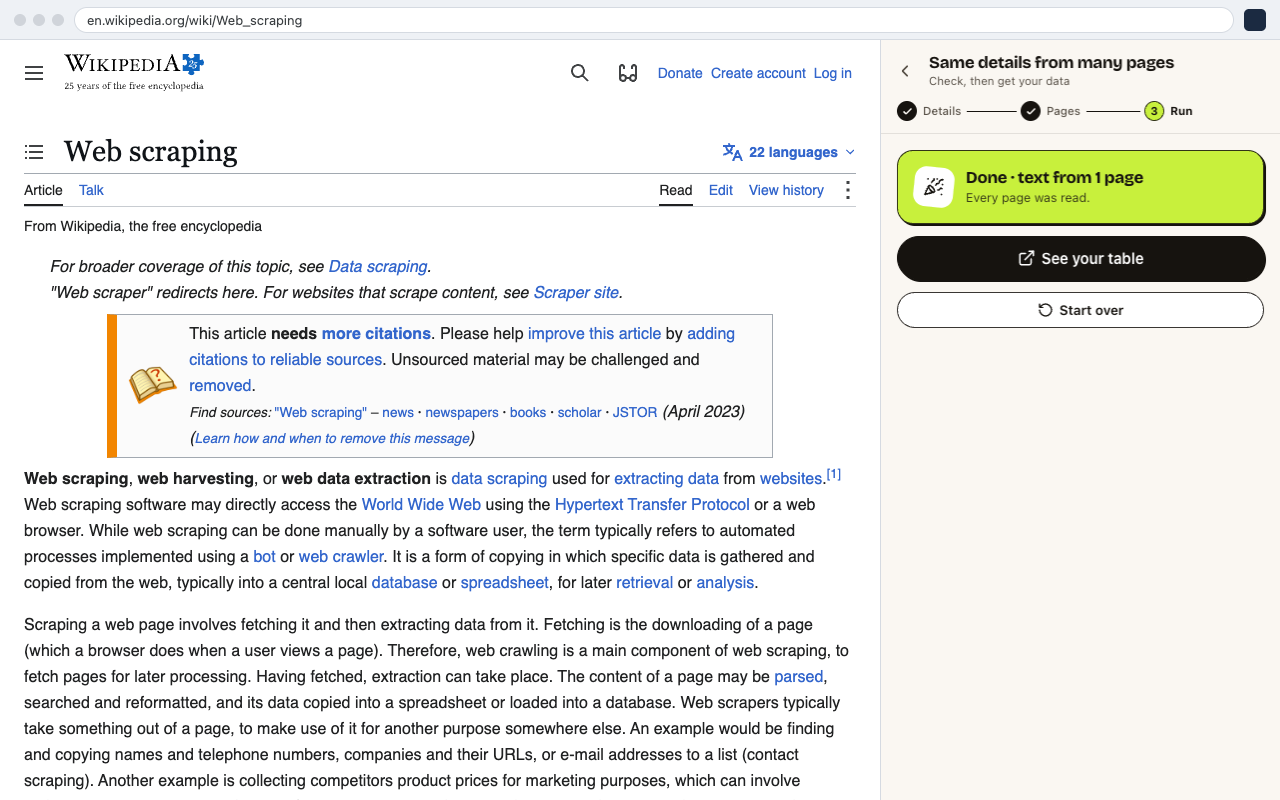
Click See your table to sort, clean and export the results. Job details shows how many pages each field was found on, so you can spot one that needs re-picking.
Lists on a Page
When a field holds several items (a list of specs or a table of variants), choose how it goes into the table under Lists in the output:
- One column: each list is one JSON column holding all its items
- Field 1 … Field 10 columns: the first 10 items, one per column
- Row per item: one row per item of the first list, with the page's other fields repeated on each row
Pages Behind a Login
CrawlPilot runs in your own Chrome session. If you're logged in to a site, it can read the same pages you can. Log in before you start. In the site's settings you can choose to Pause for me or Skip the page when a login page or an "are you human" check appears (open them from a recipe card under Recipes).
Save It as a Recipe
To run the same fields on new pages later, open the run's ⋮ menu in My data and choose Save as recipe. See Recipes.